Lanesra AI

Analytics layer for AI search on
Gemini

We track and improve how answer engines and AI agents describe your brand across every model your market uses. AEO, GEO and Agent Experience for brands and agencies worldwide.

Saas & software
E-commerce & retail
Fintech & banking
Travel & hospitality
Agencies & consultancies
B2B services

Tell us who you compete with and we will run your first scan. Then we fix what AI engines and agents get wrong about your brand

Solana›Overview
Live data

Overview

How often each brand appears in AI generated discussions

Measuring visibility on learn and discover prompts: questions that name no brand, yours or a competitor's.
Competitive scoreOne number out of 100 that blends how often AI names you, how well it speaks of you and how early you come up.
0 / 100
#2 of 23 brands · 5 pts behind the leader
VisibilityThe share of AI answers that name your brand at least once.
0%
−2 pt
Named in 24 of 96 AI answers
SentimentHow favourably AI talks about you when it names you, from 0 (badly) to 100 (glowingly).
0 / 100
Passive range · How favourably AI describes you
Share of voiceYour slice of every brand mention across the AI answers, against all the brands named.
0%
You12%
Ethereum9%
Average rankWhen an answer lists several brands, where yours usually comes. #1 means first.
#0.0
Your place among the brands an answer names
Gap to the leaderHow many times more often the most visible competitor is named than you.
1.4× Ethereum vs you
Ethereum is visible in 34% of answers, you in 25%.
You25%
Ethereum34%
When asked about you by nameWhen someone asks AI about your brand directly, how often the answer actually talks about you, and how kindly.
100%
of 30 answers name you back
67/100
sentiment
Where competitors winQuestions where AI recommends at least one competitor but leaves you out: your quickest wins.
14
prompts recommend a competitor and not you
When people look for alternatives to a competitorWhen someone asks AI for alternatives to a competitor, how often you are suggested.
18%
of 24 answers name you as an alternative
  • Alternatives to Ethereum30%
  • Alternatives to Base19%
  • Alternatives to Arbitrum6%
Visibility over timeThe share of AI answers that name each brand. Hover a bar, or a brand in the table, to pick it out.
0%9%18%27%36%
Showing the latest run
All brands (23)
BrandVisibilityThe share of AI answers that name the brand.SOVShare of voice: the brand's slice of every brand mention.
1Ethereum34%9%
2SolanaYou25%12%
3Base20%4%
4Arbitrum18%6%
5Polygon17%4%
6Optimism15%6%
7Avalanche14%5%
8Sui13%4%
9Aptos13%5%
10Near12%3%

When customers ask AI for a recommendation, does it recommend you?

For 25 years, SEO told us how we ranked. Now companies also need to know how AI sees them.

For Brands

Track your visibility across AI answers. See where you rank and where you don't.

Get early access →

For Agencies

Manage all your AEO clients in one place. Share automated, client-friendly reports that keep everyone aligned.

See partnerships →

Three numbers decide whether AI recommends you

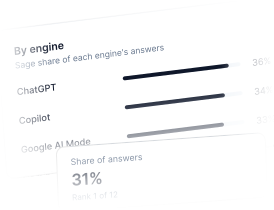
Share of answers by AI engine, with the brand ranked first of twelve

Visibility

How often you appear when your market asks. Measured across the prompts buyers actually type, not the ones you already win. Split by model and by language.

SHARE OF ANSWERS

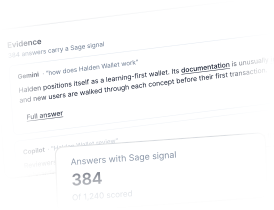
Quotes from AI answers that carry the brand's signal

Position

Where you land inside the answer. The first protocol named, or the one mentioned after the recommendation is already made. This is what tells you which prompts are winnable.

RANK INSIDE THE ANSWER

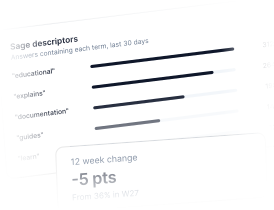
The words AI uses to describe the brand, and their change over twelve weeks

Sentiment

How the model frames you. In Web3 this is the one that costs money, because a model that hedges on your bridge security loses the reader before your docs ever load.

TRUST, SECURITY, AUDIT LANGUAGE

The working loop, start to finish

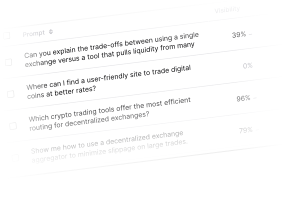
A table of tracked prompts with the brand's visibility on each

Set the prompts that matter

Bring your own or start from a generated set built around your category. Payments, staking, bridging, custody, whichever question decides your deals.

How the brand presents itself against how AI engines perceive it

See who owns the answer today

Benchmark against the protocols competing for the same prompt. Positions shift weekly, so the gap is a moving target.

The pages AI engines cite most, grouped by type of page

Find the sources models trust

Models keep citing the same handful of docs sites, aggregators and forums. Knowing which ones is the difference between guessing and shipping.

Topics, personas and the region being tracked

Choose your models and markets

Pick the engines your buyers open and the regions you sell into. Every combination is measured separately.

A ranked list of the words AI uses for the brand

Get a ranked list, not a dashboard

Each week you get a short list of what to change, with the citation data that justifies it.

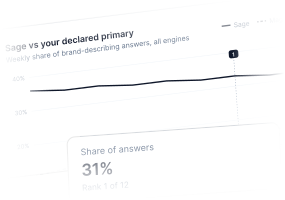
The brand's weekly share of answers as a line over time

Watch the line move

Every prompt reruns daily on every model you track, so a trend is a trend and not one lucky sample.

From first prompt to first fix in four moves

CONNECT

Add your brand

Name your protocol, your domain and the competitors you care about. No code, no tag on your site.

PROMPTS

Pick the questions

Choose the prompts your buyers ask. Start from the category set or write your own.

MEASURE

Run it daily

Every prompt runs on every model you selected, every day, in each market you track.

ACT

Fix what matters

Take the ranked list, change the docs and the sources behind it, then watch the next run.

Coverage that matches how your market actually asks

Presence by model and prompt

SAMPLE DATA, SHOWN TO ILLUSTRATE THE VIEW.

Which L1 for payments

ChatGPT21%
Gemini73%
Claude25%
Perplexity77%
Grok28%
DeepSeek80%
Copilot32%

Safest bridge 2026

ChatGPT49%
Gemini1%
Claude53%
Perplexity5%
Grok56%
DeepSeek8%
Copilot60%

fastest bridge to arbitrum

ChatGPT77%
Gemini29%
Claude81%
Perplexity32%
Grok84%
DeepSeek36%
Copilot88%

who supports staking rewards

ChatGPT5%
Gemini57%
Claude9%
Perplexity60%
Grok12%
DeepSeek64%
Copilot16%

lowest slippage dex

ChatGPT33%
Gemini85%
Claude36%
Perplexity88%
Grok40%
DeepSeek92%
Copilot44%

which wallet is most secure

ChatGPT61%
Gemini13%
Claude64%
Perplexity16%
Grok68%
DeepSeek20%
Copilot72%

Answer Engines Tracked

ChatGPTGeminiClaudePerplexityGrokDeepSeekCopilotAI OverviewsAI Mode

Languages And Market

EnglishDeutschFrancaisEspanolPortuguesTurkceKoreanJapaneseVietnamese

Web3, Understood

Protocol and token perceptionBridge and audit sentimentL1 and L2 comparisonsDocs and llms.txt readiness

Everything you need to own the AI answer

See how AI answers mention you

Track your brand visibility, sentiment and position across every major answer engine; updated daily, split by model and prompt.

Understand the tone behind the mention

Know whether the model recommends, qualifies, or dismisses you and see exactly which sentence is doing the work.

Set up prompts that matter

Build your own prompt set from real buyer questions, or start from a category template.

Discover high-value opportunities

AI-suggested prompts with estimated search volume help you focus on the questions that drive the most visibility.

Track your competitors

Add rivals and see how they rank in the same AI answers. Spot the gaps worth closing and the prompts you can win.

Choose the models that matter

Pick the answer engines your market uses; from ChatGPT to Grok, and set your tracking frequency per model.

Find key sources and act on insights

See which domains AI cites most in your category, then follow platform recommendations to close the gap, from UGC to editorial.

Fits the stack you already run

CSV

Clean exports for ad hoc reports and quick shares.

Looker Studio

Every project into a client ready dashboard through the connector.

REST API

Automate reporting and pipe visibility into your own systems.

MCP

Serve live data to Claude and any other agent you run.

Hear from the teams tracking their AI visibility with Lanesra

Thanks to @lanesra_ai, we know what answers our ICP see when asking their agents about digital asset security and compliance. With Lanesra now part of our GEO pipeline, we know where @hackenclub is placed in AI overviews, who cites us, and how to get ahead of our competitors. Ultimately, we now have clear visibility of GEO issues and a path to their remediation in AI overviews and agent replies.
Dmytro Z
Content Lead
Hacken
Great to see Hacken using Lanesra to understand how AI presents their business and where to improve. An example for the Polish ecosystem as we build towards Colosseum: solve a real customer problem and deliver value 🇵🇱
Superteam Poland
@SuperteamPOL
Superteam Poland
With Lanesra, we can see how AI presents Paybis when people ask where and how to buy crypto. We can track whether we appear in recommendations, how we’re compared with other platforms, and which sources shape those answers. That gives our team a clearer view of the gaps in our AI visibility and where to focus our GEO efforts.
Paul Afshar
CMO, Paybis
Paybis

Start tracking today

One plan. Pick your prompts, models and projects; upgrade whenever you grow.

Company Plan

Monthly Prompts

€150/moexcl. VAT

4 models • 2 projects • 160 prompts / mo

Bill MonthlySave €300
Get started

Includes a 3-day free trial.

Pay by card, SEPA Direct Debit or bank transfer.

Choose from these core models

AI Overviews
Google AI Mode
ChatGPT
Gemini
Perplexity
Copilot

Need more models?

Claude, Grok, DeepSeek, Qwen, Moonshot AI and Mistral are available as custom add-ons. Book a call →

DeepSeek
Moonshot AI
Claude
Grok
Mistral
Qwen

Everything in the Company plan

Same on every option. Only prompts, models and projects scale.

Included on all options

  • ✓6 core models (ChatGPT, Gemini, Google AI, AIO, Perplexity, Copilot)
  • ✓AI Shopping tracking & analytics
  • ✓Daily tracking & snapshot generation
  • ✓Clean CSV data exports
  • ✓Looker Studio connector integration
  • ✓Full REST API query access
  • ✓MCP (Model Context Protocol) support
  • ✓Single Sign-On (SSO) secure login
  • ✓Exclusive operator Slack community access
  • ✓Dedicated Chat & Email support

Custom - talk to sales

  • +Additional models (Claude, Grok, DeepSeek, Qwen, Moonshot AI, Mistral)
  • +Unlimited prompts, custom models & projects scaling
  • +Flexible Weekly/Monthly customized tracking
  • +Historical model reference data imports
  • +Custom enterprise whiteglove onboarding
  • +Dedicated 24/7 technical success manager

Questions, answered

Getting started?+

Add your brand and domain, choose the markets and languages you sell into, and Lanesra builds a starter set of prompts from the questions your buyers/users actually ask. Your first scores land the same day, broken out by model and language, so you can see where you already surface and where a competitor owns the answer instead. We're onboarding Web3 teams first, so the starter prompts and sovereign-model coverage come tuned for protocols, chains, exchanges and wallets out of the box.

How current are the numbers?+

Every prompt re-runs daily on each model you track, so your trend lines stay genuinely comparable day to day, real movement, not an artefact of when you opened the dashboard. That cadence matters most in Web3, our first focus industry, where a token launch or protocol upgrade can change how models describe you within a week.

Can I break the data down by model, market, or buyer type?+

Yes. Every prompt can carry tags for persona, funnel stage, market or product line, and you can filter the whole dashboard by model, country and language. That lets you ask narrow questions, how first-time buyers in the UAE see you on ALLaM in Arabic versus developers in Germany on Claude in English, without exporting anything.

Brand mentions or source citations, what's the difference?+

A mention is when an answer names you outright. A citation is when your own content shaped the answer even without naming you. We track both, because they tell you different things: one shows a model recommends you, the other shows it trusts your material enough to build its answer on it.

What's happening under the hood with citations?+

We separate two signals: when your content is used (it informed the answer) and when it's cited (your URL is named). You can drill from the domain level down to individual URLs with how often each gets pulled, so for a Web3 project you see exactly which docs, audits or third-party sources feed the answers in your category, and where to earn your next mention.

What is Agent Experience (AX), and why should we care now?+

Increasingly it isn't a person asking; it's an autonomous agent reading your docs, pricing and on-chain data to decide what to recommend or transact. Many Web3 sites are built in React or Next.js that agents struggle to parse, so you can lose a recommendation without ever seeing it. AX audits how ready your brand is for that: whether an agent can extract your key facts, whether your MCP and llms.txt surfaces are complete, and where an agent picked a rival because your answer was too thin.

Does it fit the reporting tools we already run?+

Three ways in: a Looker Studio connector for drag-and-drop dashboards, a REST API for custom pipelines, and MCP to feed visibility straight into agents like Claude, which is also how the Agent Experience loop closes. All three stream live, so the numbers stay current instead of freezing at export.

Why does a Web3 team need this more than a typical brand?+

Because the models start at a disadvantage with crypto. Their training data lags months behind your last upgrade, they routinely confuse similar token names and misattribute features, and they've absorbed a lot of skeptical coverage; rug pulls, enforcement actions, failed launches; that colours how they describe the whole category. Lanesra shows you exactly where that's happening to your project so you can correct it at the source.

Do you track the region's own AI models, not just the American ones?+

Yes; that's a core reason teams pick us. Alongside ChatGPT, Gemini, Claude, Perplexity and Grok, we track the sovereign models your GCC buyers actually use, Jais, ALLaM, Fanar and Falcon-H1, and we measure Arabic answers natively rather than through translation, because a model's Arabic answer is genuinely different from its English one.

More

Start Here

See where you stand in AI answers before your competitors do

Start a free trial. Tell us your category and we will run the first scan.